VERAA's LLM mapped numerical income-range responses least accurately (B1 income 70-75%)
Source
Rishivardhan Krishnamoorthy (2024). Voice-Enabled Response Analysis Agent (VERAA): Leveraging Large Language Models to Map Voice Responses in SDoH Survey. AMIA Joint Summits on Translational Science.
Description #
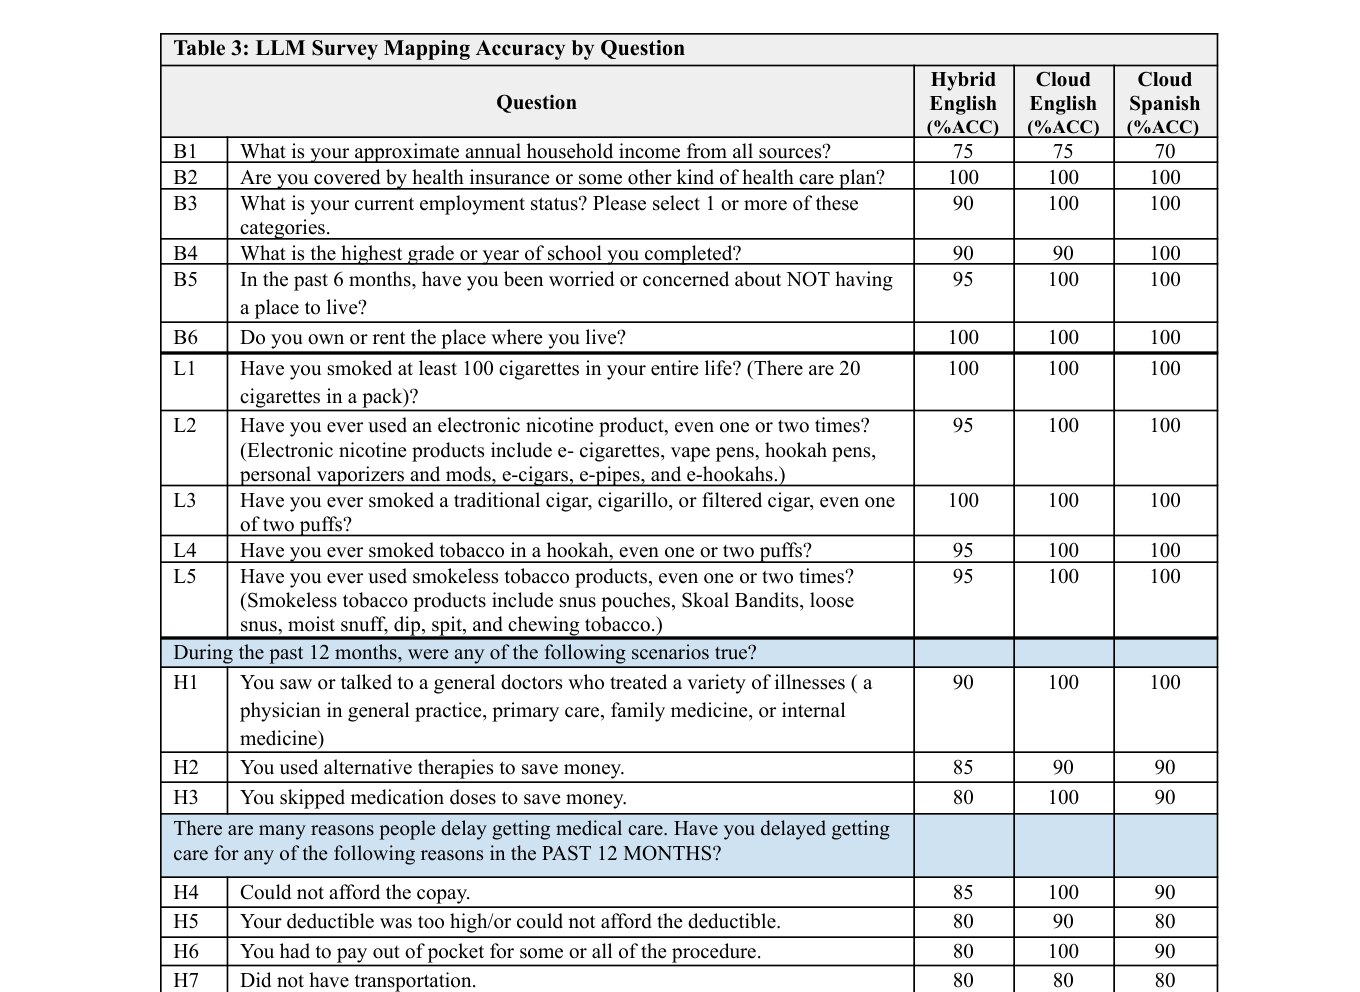 VERAA's Llama-2 mapping was least accurate on the question requiring a numerical (relational) comparison — mapping a spoken income figure to the correct annual-household-income bin (question B1), which scored 75% (Hybrid English), 75% (Cloud English), and 70% (Cloud Spanish), the lowest of any question in each configuration (Table 3). The authors report that Llama-2 could match a response only when the income equalled a bin's boundary, not when it fell within the range, indicating the LLM could not perform relational operations on numerical values.
"It can be observed that the performance of Llama-2 is discernibly lower when the questions involve mathematical comparisons (e.g., question B1). For example, the task in question B1 is for the LLM to match the patient's response to the correct bin of annual household income range. Llama-2 can correctly match the response when the annual income is equal to the lower or upper bound of the range, but not when it is within the range. This suggests that Llama-2 lacks the ability to perform relational operations on numerical values." (Krishnamoorthy, 2024, p. 261)
Methods Context #
What? #ⓘ
The observable: per-question mapping accuracy (ACC) for question B1, which requires mapping a stated household-income amount to one of ten income-range bins (Table 2).
"What is your approximate annual household income from all sources?" (Krishnamoorthy, 2024, p. 262, Table 3)
How? #ⓘ
The LLM was given the transcribed income response and instructed to select the matching structured income-range bin; accuracy was scored against the reviewer consensus ground truth across the three pipeline configurations. See A-0019ArtifactA-0019Initial AI draftVERAA (Voice-Enabled Response Analysis Agent)Why might someone use this thing? The Voice-Enabled Response Analysis Agent (VERAA) is a multilingual, voice-based conversational agent, embedded in the bedside "My Companion Pet" (MCoPet) edge-computing device, designed….
"The transcribed text is then passed to Llama-2 with instructions to map the text to the most appropriate survey response." (Krishnamoorthy, 2024, p. 260)
Who? #ⓘ
Question B1 (annual household income, from the All of Us "The Basics Survey") evaluated across 20 English and 10 Spanish scripted responses; the ten income bins are enumerated in Table 2 (from "Less than $10,000" to "$200,000 or more").
"For each of the 28 questions, we generated 10 distinct scripted replies encompassing all answer choices (i.e, a total of 280 potential responses)." (Krishnamoorthy, 2024, p. 259)
Other Notes #
This finding is a limitation of the LLM-mapping step specifically (independent of transcription/translation), since B1 was the lowest-scoring question even in the Cloud English pipeline that scored 100% on most questions. The authors note the pattern is consistent with prior work showing LLMs err on certain math-question formulations.