Cloud-based VERAA mapped English voice survey responses to structured SDoH answers at 100% median accuracy
Source
Rishivardhan Krishnamoorthy (2024). Voice-Enabled Response Analysis Agent (VERAA): Leveraging Large Language Models to Map Voice Responses in SDoH Survey. AMIA Joint Summits on Translational Science.
Description #
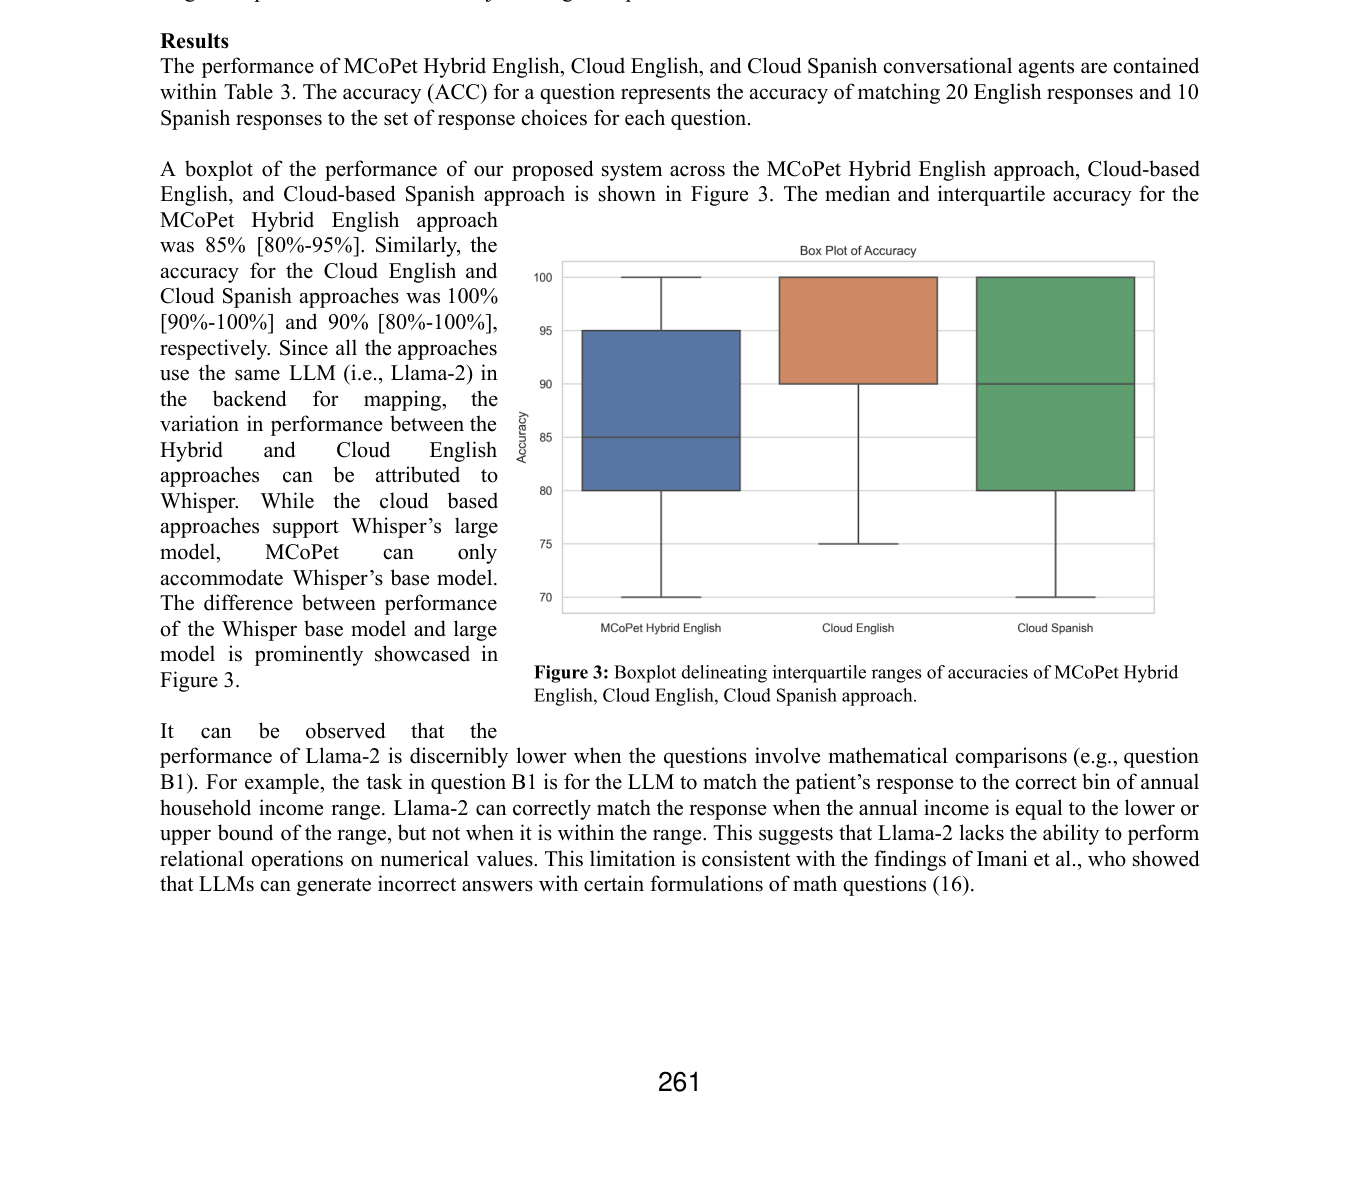
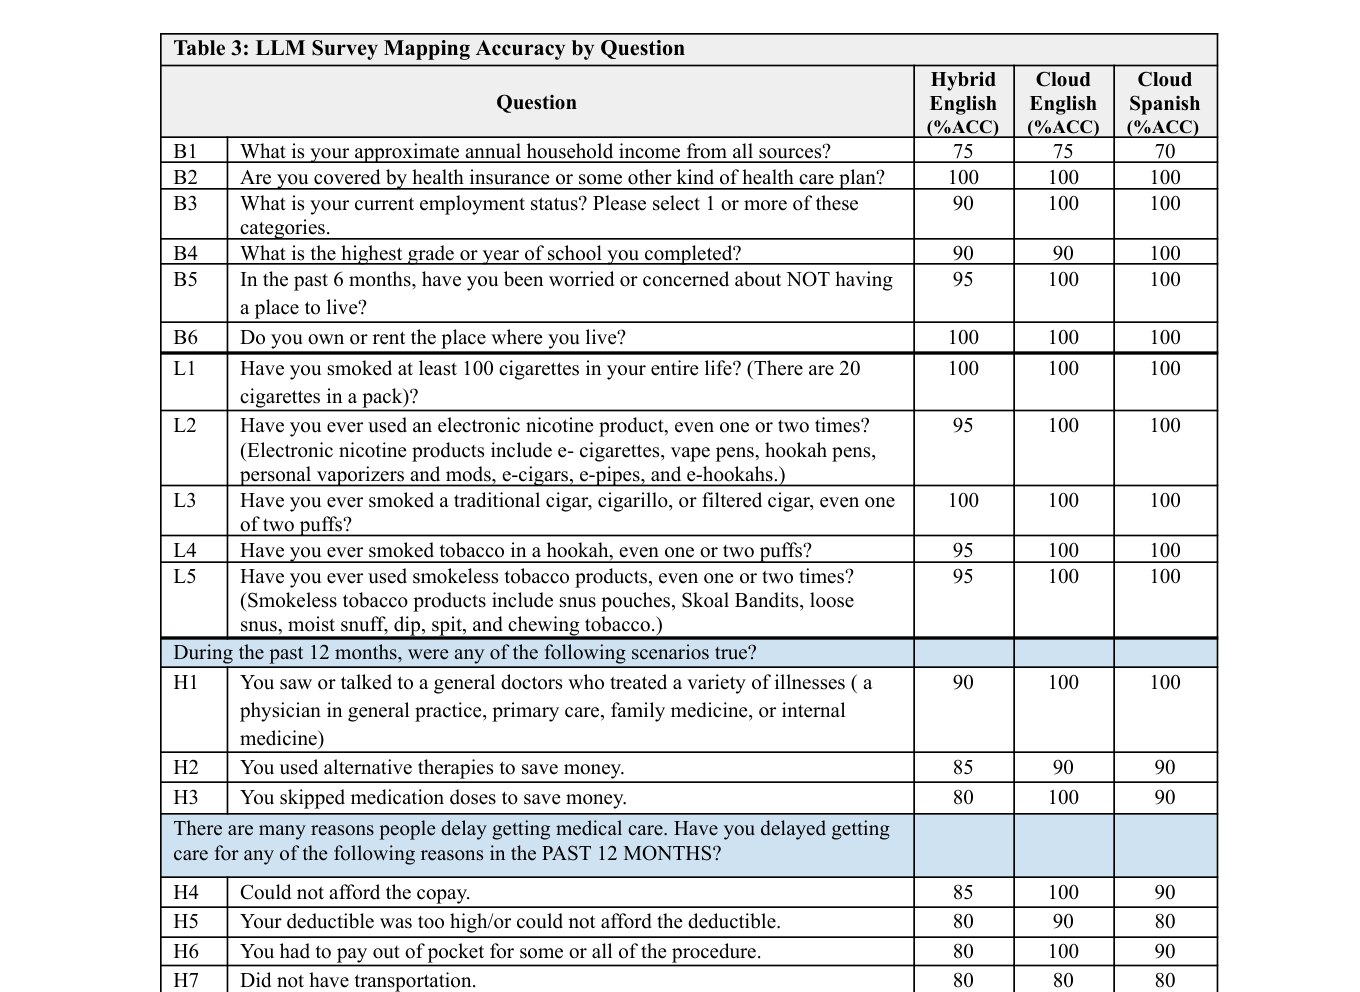 Using the cloud-based pipeline (Whisper large model + Llama-2 70B on AWS), VERAA mapped scripted English voice responses to the correct structured SDoH survey answer choices with a median per-question accuracy of 100% (interquartile range 90%–100%) across the 28 questions (Fig. 3; Table 3). Cloud English was the highest-performing of the three configurations tested.
"The median and interquartile accuracy for the MCoPet Hybrid English approach was 85% [80%-95%]. Similarly, the accuracy for the Cloud English and Cloud Spanish approaches was 100% [90%-100%] and 90% [80%-100%], respectively." (Krishnamoorthy, 2024, p. 261)
"Boxplot delineating interquartile ranges of accuracies of MCoPet Hybrid English, Cloud English, Cloud Spanish approach." (Krishnamoorthy, 2024, p. 261, Fig. 3)
Methods Context #
What? #ⓘ
The observable: per-question mapping accuracy (ACC) — the proportion of spoken responses correctly matched to the discrete survey answer choices, benchmarked against a human consensus "ground truth."
"The accuracy (ACC) for a question represents the accuracy of matching 20 English responses and 10 Spanish responses to the set of response choices for each question." (Krishnamoorthy, 2024, p. 261)
"Each of the 280 scripted responses were examined by a panel of three reviewers who through consensus mapped the scripted response to one of the structured survey answers. This "ground truth" was then used for evaluating the LLM's mapping accuracy." (Krishnamoorthy, 2024, p. 260)
How? #ⓘ
Scripted English audio responses were transcribed by Whisper's large model and mapped to structured answers by Llama-2 70B, both hosted on a cloud AWS GPU instance; accuracy was scored against the reviewer consensus ground truth. See A-0019ArtifactA-0019Initial AI draftVERAA (Voice-Enabled Response Analysis Agent)Why might someone use this thing? The Voice-Enabled Response Analysis Agent (VERAA) is a multilingual, voice-based conversational agent, embedded in the bedside "My Companion Pet" (MCoPet) edge-computing device, designed….
"In the second and third experiments, the English and Spanish audio files were passed to the AWS instance where Whisper's large model (1.550 Billion parameters) was used to produce audio transcription that Llama-2 70B used for inference." (Krishnamoorthy, 2024, p. 261)
Who? #ⓘ
The English dataset comprised 20 scripted English audio responses per question across 28 SDoH questions derived from four publicly available All of Us surveys (Basics, Lifestyle, Healthcare Access and Utilization, Overall Health); no real patients were involved.
"A panel of two English speakers and one Spanish speaker then read the generated scripts for a total of 20 English audio responses and 10 Spanish audio responses per question." (Krishnamoorthy, 2024, p. 259)
Other Notes #
The 100% median is a per-question median across 28 questions; individual questions ranged lower (e.g., B1 income at 75%; see the numerical-comparison EVD). Accuracy was evaluated on pre-formed scripted responses, not spontaneous patient speech.
Caveats #
- VERAA was evaluated on scripted pre-formed responses, not spontaneous patient speech The reported mapping accuracies were obtained on a fixed set of pre-formed, scripted responses read aloud by a small panel of speakers, not on spontaneous, "wild type" answers from real patients. Scripted responses were used specifically so that accuracy could be compared across languages and speakers given the same response, but they under-represent the variability, disfluency, dialect, accent, and open-endedness of genuine patient speech. The full range of real-world responses therefore remains unevaluated, so the high accuracies may not transfer to deployment with actual patients.