iTranslate and human Chinese translations differed only slightly with all sentences reaching excellent-to-perfect fluency
Source
Chen (2017). Machine or Human? Evaluating the Quality of a Language Translation Mobile App for Diabetes Education Material. JMIR Diabetes.
Description #
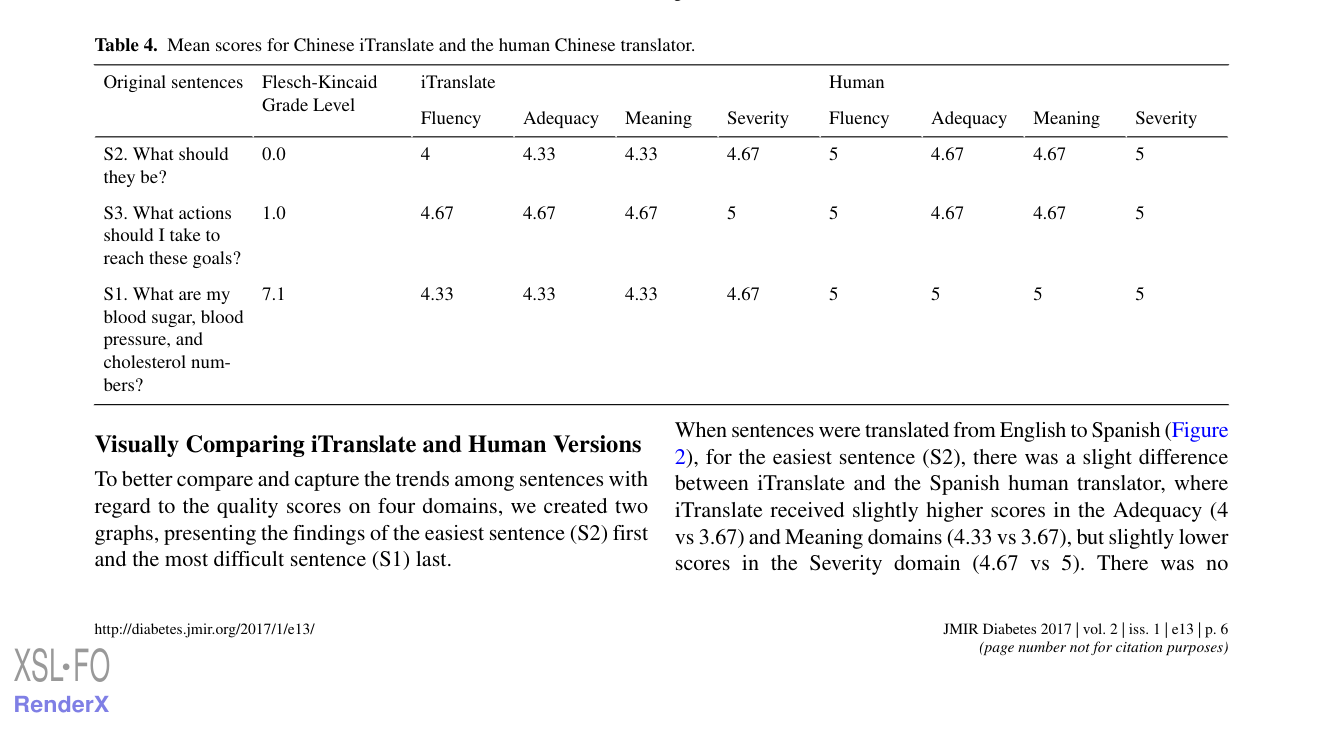
 On blinded evaluation of English-to-Chinese (Mandarin) translations of the same three diabetes-education sentences, iTranslate and the professional human translator differed only slightly across all three sentences. Every sentence translated by both iTranslate and the human reached excellent or perfect fluency, conveyed 75-100% of the original information, and had almost no effect on patient care; where differences existed (the easiest sentence S2 and the most difficult S1), iTranslate scored slightly lower than the human across all four domains (Table 4; Fig. 3).
"As shown in Table 4, within the Fluency domain, all the sentences translated by both iTranslate and the Chinese human translator had excellent or perfect fluency. Within the Adequacy domain, all the sentences conveyed more than 75% to 100% of the original information. Within the Meaning domain, all the sentences had (almost) the same meaning as the original. Within the Severity domain, all the sentences had almost no effect on patient care." (Chen, 2017, p. 6)
"For the easiest sentence (S2) and the most difficult sentence (S1), there was a slight difference between iTranslate and the Chinese human translator, where iTranslate received slightly lower scores in all the four domains." (Chen, 2017, p. 6)
Methods Context #
What? #ⓘ
The observable: translation quality of each sentence, scored by raters on four 5-point criteria — Fluency, Adequacy, Meaning, and Severity.
"instructed the raters to evaluate the translated sentences based on four criteria—Fluency, Adequacy, Meaning, and Severity—on a 5-point scale (1 indicates the lowest quality and 5 indicates the highest quality)." (Chen, 2017, p. 4)
How? #ⓘ
Certified medical translators scored the A-0015ArtifactA-0015Initial AI draftiTranslate voice-enabled mobile language translation appTo help patients and health care providers communicate across a language barrier by instantly converting spoken or written input into another language, so that individuals with limited English proficiency (LEP) can acces… version and the professional-human version of each sentence, blinded to which was which by labeling the audio files "version 1" (iTranslate) and "version 2" (human).
"To minimize rater bias and blind the evaluation process, the audio files were marked as version 1 (sentences translated by iTranslate) and version 2 (sentences translated by a human)." (Chen, 2017, p. 4)
Who? #ⓘ
Three American Translators Association (ATA)-certified Chinese medical translators evaluated the Chinese (Mandarin) translations; the material was three spoken questions drawn from a publicly available diabetes patient-education pamphlet.
"We recruited six certified medical translators (three Spanish and three Chinese) to conduct blinded evaluations of the following versions: (1) sentences interpreted by iTranslate, and (2) sentences interpreted by the professional human translators." (Chen, 2017, p. 1)
"We used iTranslate app to translate three spoken questions from English into both Spanish and Chinese (Mandarin)." (Chen, 2017, p. 3)
Other Notes #
On the most difficult Chinese sentence (S1), iTranslate omitted the word "number," which cost it full Fluency, Adequacy, and Meaning scores — but all raters still judged the difference minor and without effect on patient care. This is a translation-quality (accuracy) rating by expert translators, not a comprehension outcome measured in LEP patients. The authors explicitly declined to conclude that iTranslate is more accurate for Chinese than for Spanish.
Caveats #
- Pilot evaluation of only three short sentences in two languages judged by translators not LEP patients This was a pilot study whose evidence rests on only three short spoken sentences from a single diabetes patient-education pamphlet, translated into just two languages (Spanish and Chinese). Because the sentence sample is so small and language-limited, the authors caution the findings should not be generalized to other languages or to longer, real-world clinical communication. In addition, translation quality was rated by certified translators rather than measured as comprehension or outcomes in actual LEP patients, so the app's usefulness in real patient encounters remains untested.