Google Translate and professional translation did not differ in meaning (connotation) preservation of a Spanish warfarin brochure
Source
Khanna (2011). Performance of an online translation tool when applied to patient educational material. Journal of Hospital Medicine.
Description #
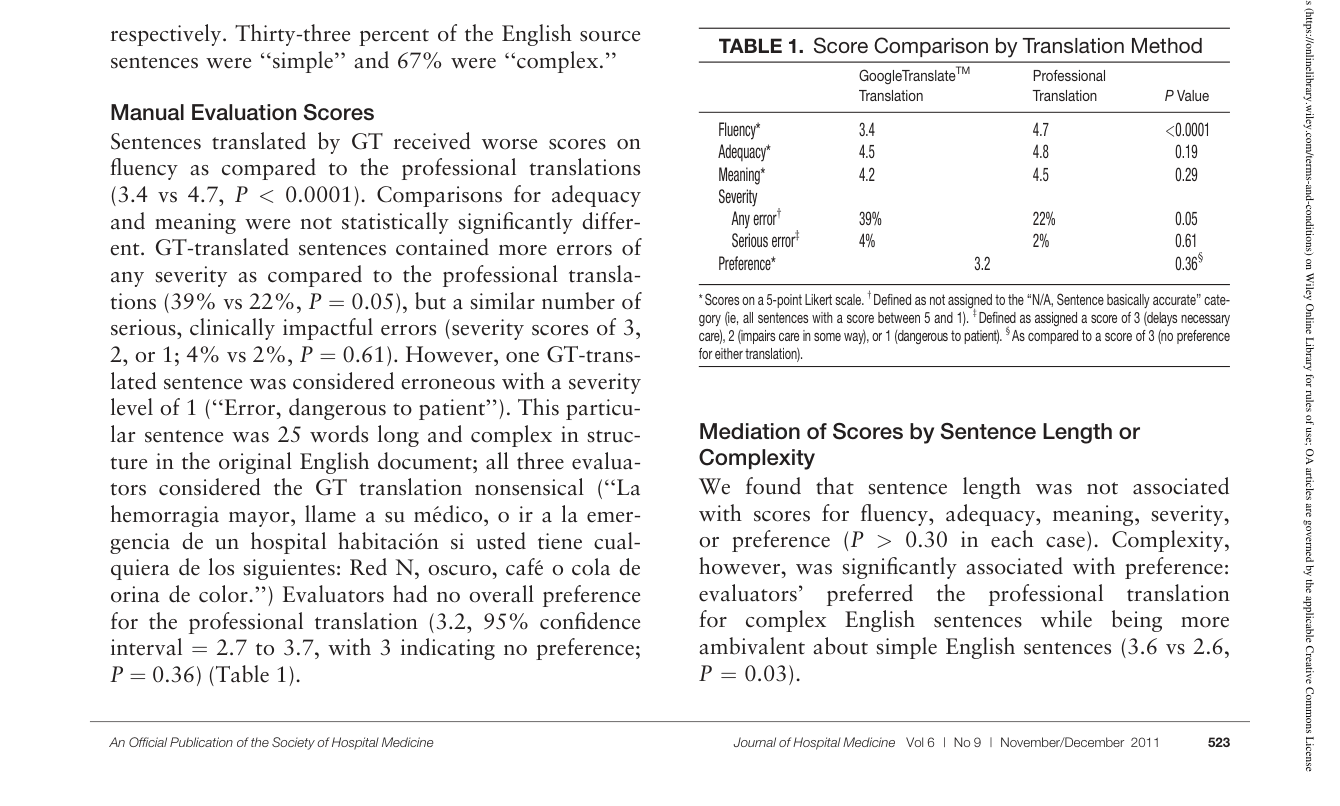 Google Translate (GT) and professional Spanish translations of the AHRQ warfarin brochure did not differ significantly on meaning — maintenance of connotation and intent — with GT scoring 4.2 versus 4.5 for the professional translation (P = 0.29) (Table 1). GT generally preserved the sense of the original text.
"In summary, GT scored worse in grammar but similarly in content and sense to the professional translation, committing one critical error in translating a complex, fragmented sentence as nonsense." (Khanna, 2011, p. 525)
Methods Context #
What? #ⓘ
The observable: meaning, a Likert rating of whether the translation maintained the connotation and intent of the original sentence.
"we asked evaluators to assess meaning, a measure of connotation and intent maintenance, with scores ranging from 5 ("Same meaning as original") to 1 ("Totally different meaning from the original")." (Khanna, 2011, p. 520)
How? #ⓘ
Blinded sentence-level scoring of A-0016ArtifactA-0016Initial AI draftGoogle TranslateA free, general-purpose machine translation app increasingly used as an ad-hoc communication tool in healthcare settings to bridge language barriers with LEP patients, including via voice-to-voice translation. "One such… against the professional translation, with the original English sentence available for reference, compared via clustered linear regression.
"evaluators compared the GT and professional translations of the same sentence (with the original English sentence available as a reference) and indicated a preference, for any reason, for one translation or the other." (Khanna, 2011, p. 521)
Who? #ⓘ
Forty-five sentences from the professionally prepared AHRQ warfarin-use instruction manual, each scored by three nonclinician bilingual native-Spanish-speaking research assistants of Mexican, Nicaraguan, and Guatemalan ancestry.
"The evaluators were all college educated with a Bachelor's degree or higher and were of Mexican, Nicaraguan, and Guatemalan ancestry." (Khanna, 2011, p. 520)
Other Notes #
This is a null (no-difference) result supporting an equivalence claim on meaning preservation. Note a source inconsistency: Table 1 reports meaning as GT 4.2 vs professional 4.5 (P = 0.29), whereas the abstract reports the meaning point estimates as 4.5 vs 4.8; the adequacy and meaning point estimates appear transposed between the abstract and Table 1, though both agree the comparison was non-significant. Meaning was among the domains with poorer interrater reliability (see qualifying caveat).
Caveats #
- Translation quality was judged by nonclinician evaluators, not patients, so comparable scores may not mean comparable patient comprehension Translation quality was rated by three college-educated, bilingual, nonclinician research assistants comparing sentences against the English source — not by the limited-English-proficiency patients who would actually read the material. Patients may have lower or more variable medical understanding and educational attainment than the evaluators, so the finding that machine and professional translations scored comparably on adequacy and meaning does not establish that patients would understand them equally well. Comparable expert-rated quality is an upstream proxy for, not a measurement of, patient comprehension.
- The evaluated document was a professionally prepared brochure, not the spontaneous patient-specific text machine translation would actually be used for The material tested was a carefully, professionally prepared AHRQ patient-education brochure written at a 6th-grade reading level — precisely the kind of standardized document for which a professional translation would normally already exist. The authors note that online translation tools would most likely be deployed not for such material but for spontaneous, less-critical, patient-specific instructions, which may have different grammar, vocabulary, and error profiles. The comparable-quality finding therefore may not transfer to machine translation's intended real-world use case.
- Interrater reliability was only moderate, with meaning and preference domains scoring particularly poorly The manual scoring system had only moderate interrater reliability, and the meaning and preference domains in particular scored poorly (intraclass correlations of 0.42 for meaning and 0.37 for preference, versus 0.70 for fluency). Because evaluators frequently disagreed on meaning and on which translation they preferred, the null findings on meaning preservation and on overall preference — and the complexity-dependent preference pattern — rest on comparatively noisy measurements and warrant more thorough assessment before routine use.