Machine translation assessed both pain and nausea every time in 76.7% of LEP PACU patients
Source
Kapoor (2022). Use of Neural Machine Translation Software for Patients With Limited English Proficiency to Assess Postoperative Pain and Nausea. JAMA.
Description #
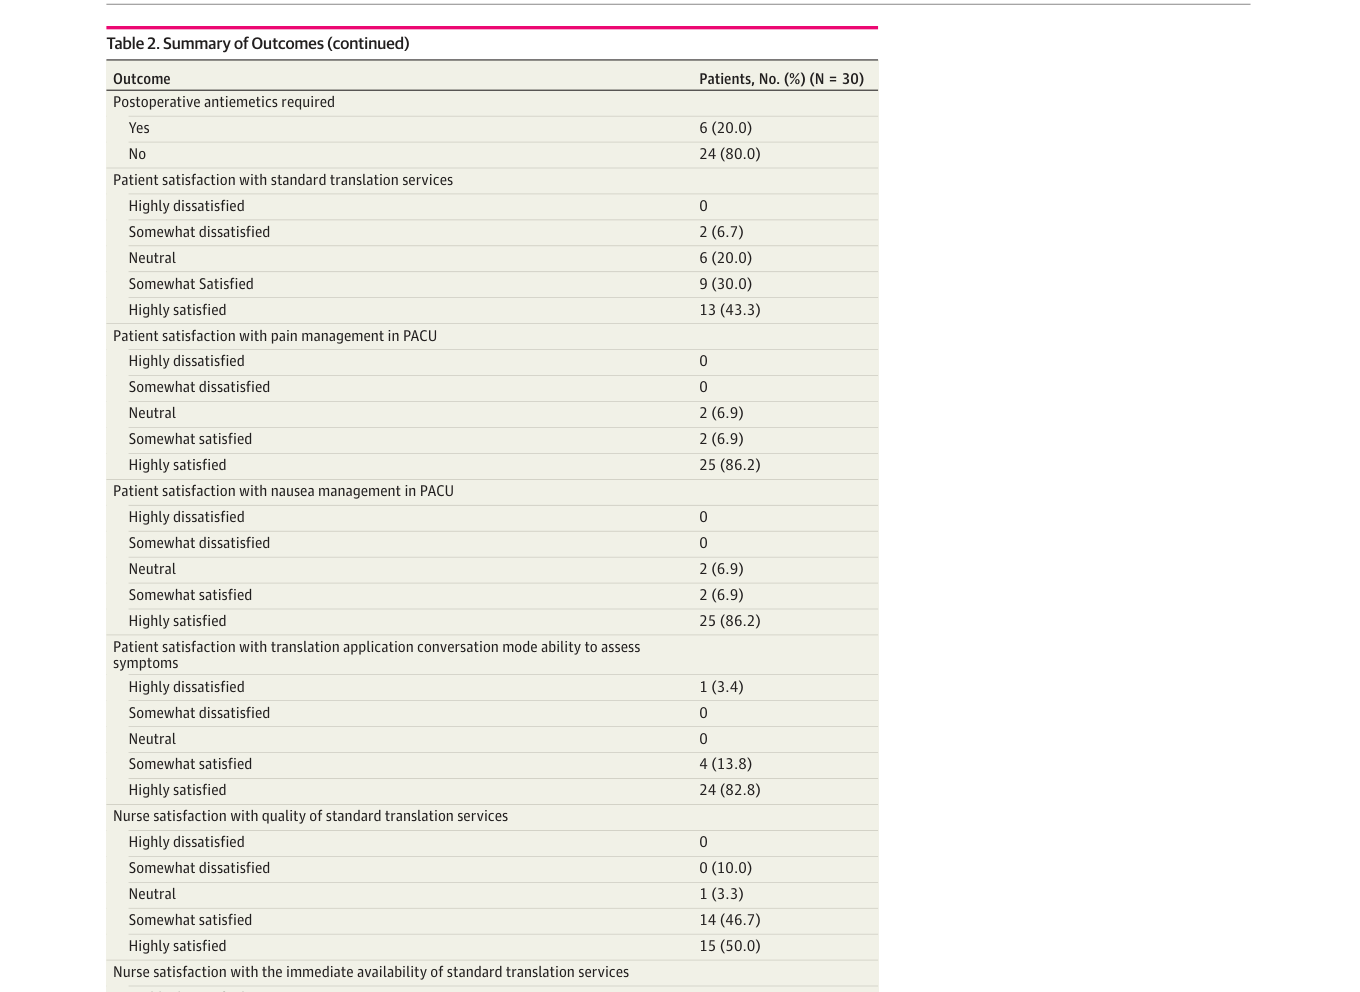 Across the entire postanesthesia care unit (PACU) stay, the Google Translate conversation mode successfully assessed both postoperative pain and nausea every single time in 76.7% of the 30 Spanish-speaking LEP patients (i.e., 23 of 30 "did not ever fail"); the remaining 13.3% (4 of 30) failed at least once for pain and nausea combined (Table 2). Taken separately, the every-time success rate was 80.0% for pain and 83.3% for nausea. This every-time rate fell below the study's prespecified 90.0% feasibility threshold.
"The success rate during the entire PACU stay at evaluating postoperative pain and nausea every time was 76.7%. Separately, 80.0% and 83.3% of patients could be assessed using the application every time for pain or nausea, respectively." (Kapoor, 2022, p. 4)
Methods Context #
What? #ⓘ
The observable: whether the translation application could evaluate postoperative pain and nausea on every assessment attempt during the PACU stay (an every-time success rate).
"The success rate during the entire PACU stay at evaluating postoperative pain and nausea every time was 76.7%." (Kapoor, 2022, p. 4)
How? #ⓘ
Single-arm feasibility cohort: an iPad running the A-0016ArtifactA-0016Initial AI draftGoogle TranslateA free, general-purpose machine translation app increasingly used as an ad-hoc communication tool in healthcare settings to bridge language barriers with LEP patients, including via voice-to-voice translation. "One such… played preformatted Spanish pain/nausea questions at intervals when nurses would normally assess symptoms, with success tallied over the whole PACU stay; feasibility was prespecified as ≥90% of patients answering all 5 questions.
"Preformatted questions were played for patients in the PACU through the application using an iPad tablet (Apple) held by the research coordinator (G.C., M.P.F.) at set intervals when nurses would typically evaluate symptoms." (Kapoor, 2022, p. 4)
"Use of the translation application conversation mode was considered feasible if at least 90.0% of patients were able to answer all 5 questions asked." (Kapoor, 2022, p. 4)
Who? #ⓘ
30 postoperative patients in the PACU at a single US cancer center, all Spanish-speaking and self-identified as Hispanic, undergoing a mix of surgery types (gastrointestinal, urologic, breast oncology, thoracic, others).
"Among 30 patients (median [IQR] age, 62 [53-80] years; 15 [50.0%] men) who were enrolled, all spoke only Spanish and self-identified as Hispanic (Table 1)." (Kapoor, 2022, p. 4)
Other Notes #
The two side-by-side metrics in this paper (every-time 76.7% vs at-least-once 96.7%) diverge; this EVD captures the stricter every-time metric that maps to the prespecified feasibility criterion, and the companion at-least-once EVD captures the headline "more than 90%" figure the authors emphasize in the Discussion.
Caveats #
- Machine-translation assessment tested in only one language (Spanish) All assessments were conducted in a single language: every enrolled patient spoke only Spanish and self-identified as Hispanic. Neural machine translation quality varies substantially by language pair, and Spanish is one of the highest-resource, best-supported languages for engines such as Google Translate. Feasibility and satisfaction observed here therefore may not transfer to lower-resource languages where translation accuracy is poorer, so the findings should not be read as evidence that the tool works equally well across the 70 languages the application nominally supports.
- Machine-translation feasibility shown only in a 30-patient single-center cohort The feasibility, usability, and satisfaction estimates all come from a single-arm cohort of only 30 patients at one US cancer center, with no comparison group. The authors themselves flag the small sample size, which yields wide confidence intervals (they estimated the 95% CI for a 90% feasibility rate spanned 73.5% to 97.9%) and limits how precisely any of the reported proportions can be interpreted or generalized to other settings.